Launches
NVIDIA previews 2.8 trillion Indic tokens, with an open recipe to make more
Developing 4 sources
NVIDIA and AI4Bharat's announced synthetic Indic pretraining corpus, paired with a public NeMo Data Designer translation and evaluation plugin.
What happened lately
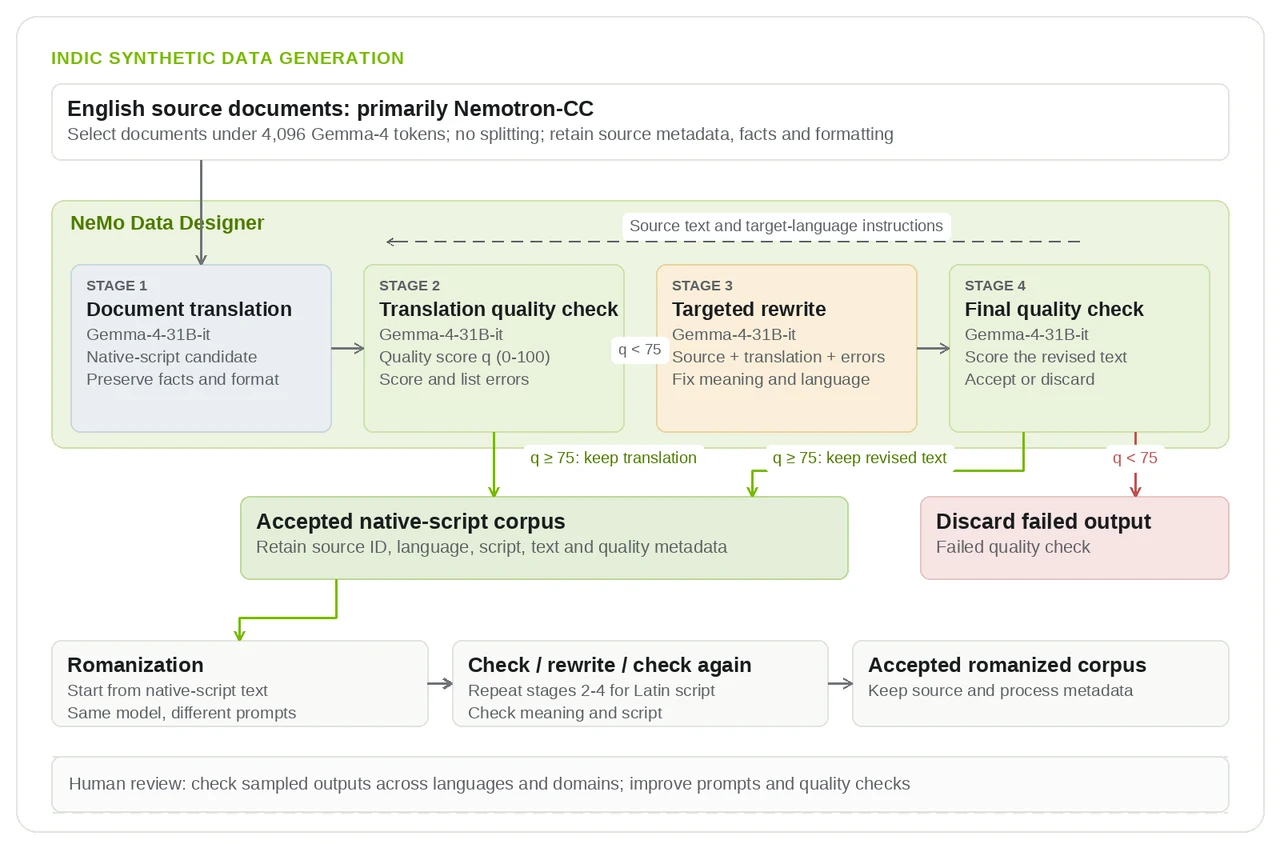
NVIDIA and AI4Bharat at IIT Madras describe approximately 2.8 trillion synthetic pretraining tokens across 22 Indian languages. Their October 16 announcement says the corpus is releasing soon; this record does not establish that the complete corpus is already downloadable.
The public translation plugin runs inside NeMo Data Designer and translates, evaluates and optionally rewrites source documents. Its repository package specifies Python 3.10 or newer, Data Designer 0.9.4 or newer and Apache-2.0 licensing. Model inference and corpus licensing are separate from that plugin license. The announced corpus includes native-script text for 22 languages and romanized subsets for twelve, derived from curated English source material.