SafeDecide's small model knows when to hand off
A 140M decision model pairs option probabilities with an automate-or-escalate gate, backed by a conditional calibration guarantee.
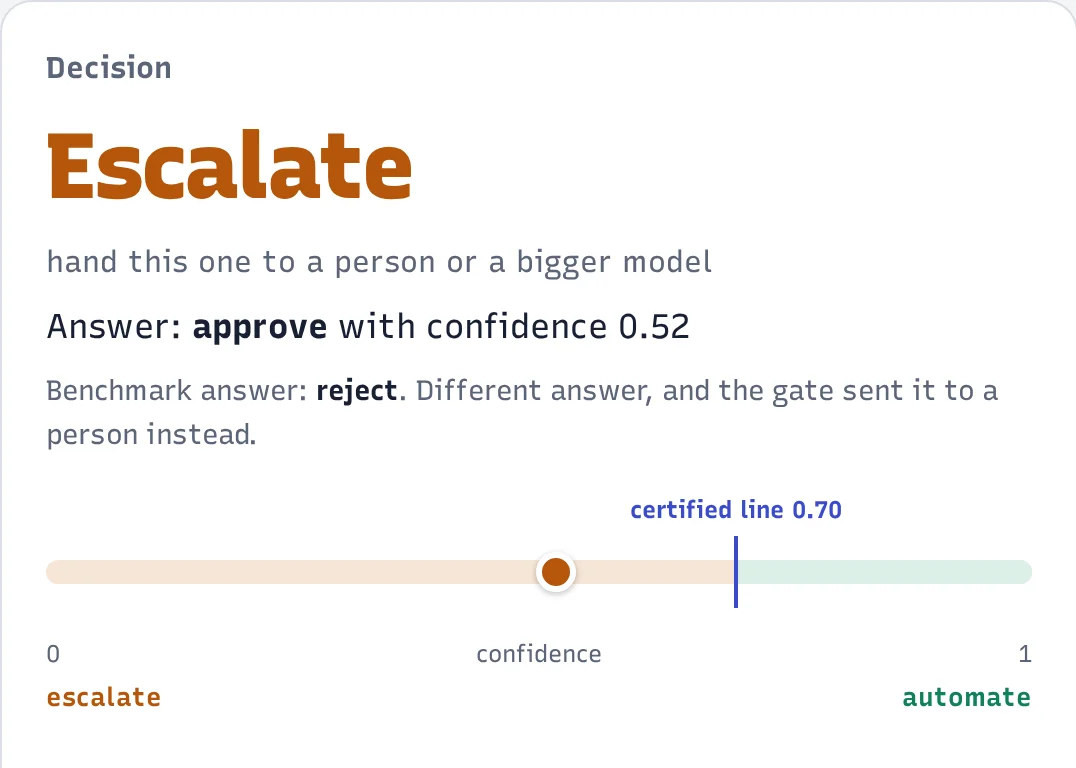
SafeDecide pitches a different job for a small AI model: deciding when its own answer should be handed off. Yotam Braun’s 140-million-parameter community checkpoint scores typed questions and returns an automate or escalate flag alongside probabilities. Its public Hugging Face repository appeared October 18.
The author’s phrase is a model that “knows when not to decide.” The mechanism is more specific: a library tests confidence thresholds against labeled calibration data, then selects a threshold it can certify for a chosen error budget. It supports yes/no, pick-one and ordinal-score questions rather than open-ended generation.
A useful gate with a conditional promise
At the default 10% error budget, the shipped threshold is 0.70. The model card says applying it unchanged to 2,000 held-out typed-decisions test decisions automated 26.2%, with 4.4% of those answers wrong. A separate 100-split calibration experiment reports 33.2% average automation; that is a different protocol, not the shipped threshold’s result.
The stated guarantee is conditional: with at least 90% probability over the calibration draw, error among automated decisions is at most 10%, for data exchangeable with the calibration set. It is not a promise that each customer, task or answer has that error rate. The project recommends recalibrating on labeled examples from the intended workflow.
The release makes the failure mode visible. In one distribution-shift experiment using a 5% budget, error among automated decisions rose to 8.39%. The reference labels also come from a teacher model, so benchmark error measures disagreement with that reference, not independently established real-world truth.
Local deployment, with export caveats
The Python 3.11-or-newer library documents pip install "safedecide[all]", local model loading and a /v1/systemone HTTP interface. The released checkpoint is labeled Apache-2.0. The library can also calibrate other decision models from confidence scores and correctness labels.
ONNX and browser-oriented deployment are described, but the smaller int8 export changes logits. Its automation flags are outside the shipped full-precision guarantee until recalibrated. The project explicitly excludes fully automated legal, medical, financial or employment decisions affecting people.
AITrending reviewed the English card and library documentation without running the model. This is a concrete small-model routing and calibration workflow, not a general reasoning model or an unconditional safety certificate.
Related reading
Decima Guard brings multilingual prompt checks to a CPU