Launches
LoCo-7B learns when to stop thinking, reporting 45% fewer math tokens
Community reports 5 sources
A DeepSeek-R1-Distill-Qwen-7B fine-tune trained to shorten reasoning using preferences at intermediate states.
What happened lately
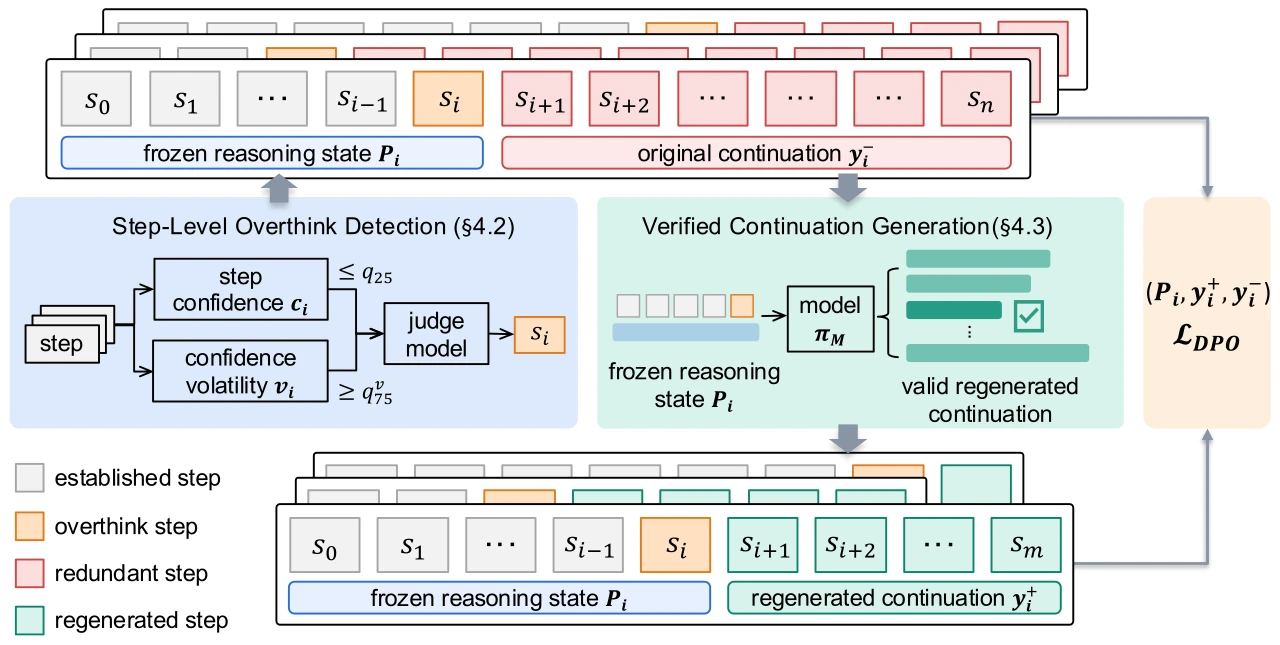
LoCo-7B is a reasoning-compressed fine-tune of DeepSeek-R1-Distill-Qwen-7B. Its authors construct preference pairs from math traces at selected intermediate reasoning states, teaching the model to favor shorter answer-verified continuations. Their November 3 paper reports reduced completion length on mathematics and code benchmarks after math-only training. Those are author-run results, with a slight accuracy decline on MATH500, rather than independent confirmation or a guarantee across tasks. The public repository contains BF16 Safetensors weights, and its English card supplies a vLLM usage example. “Local” refers to reasoning states, not a claim that it fits any particular personal computer.