Launches
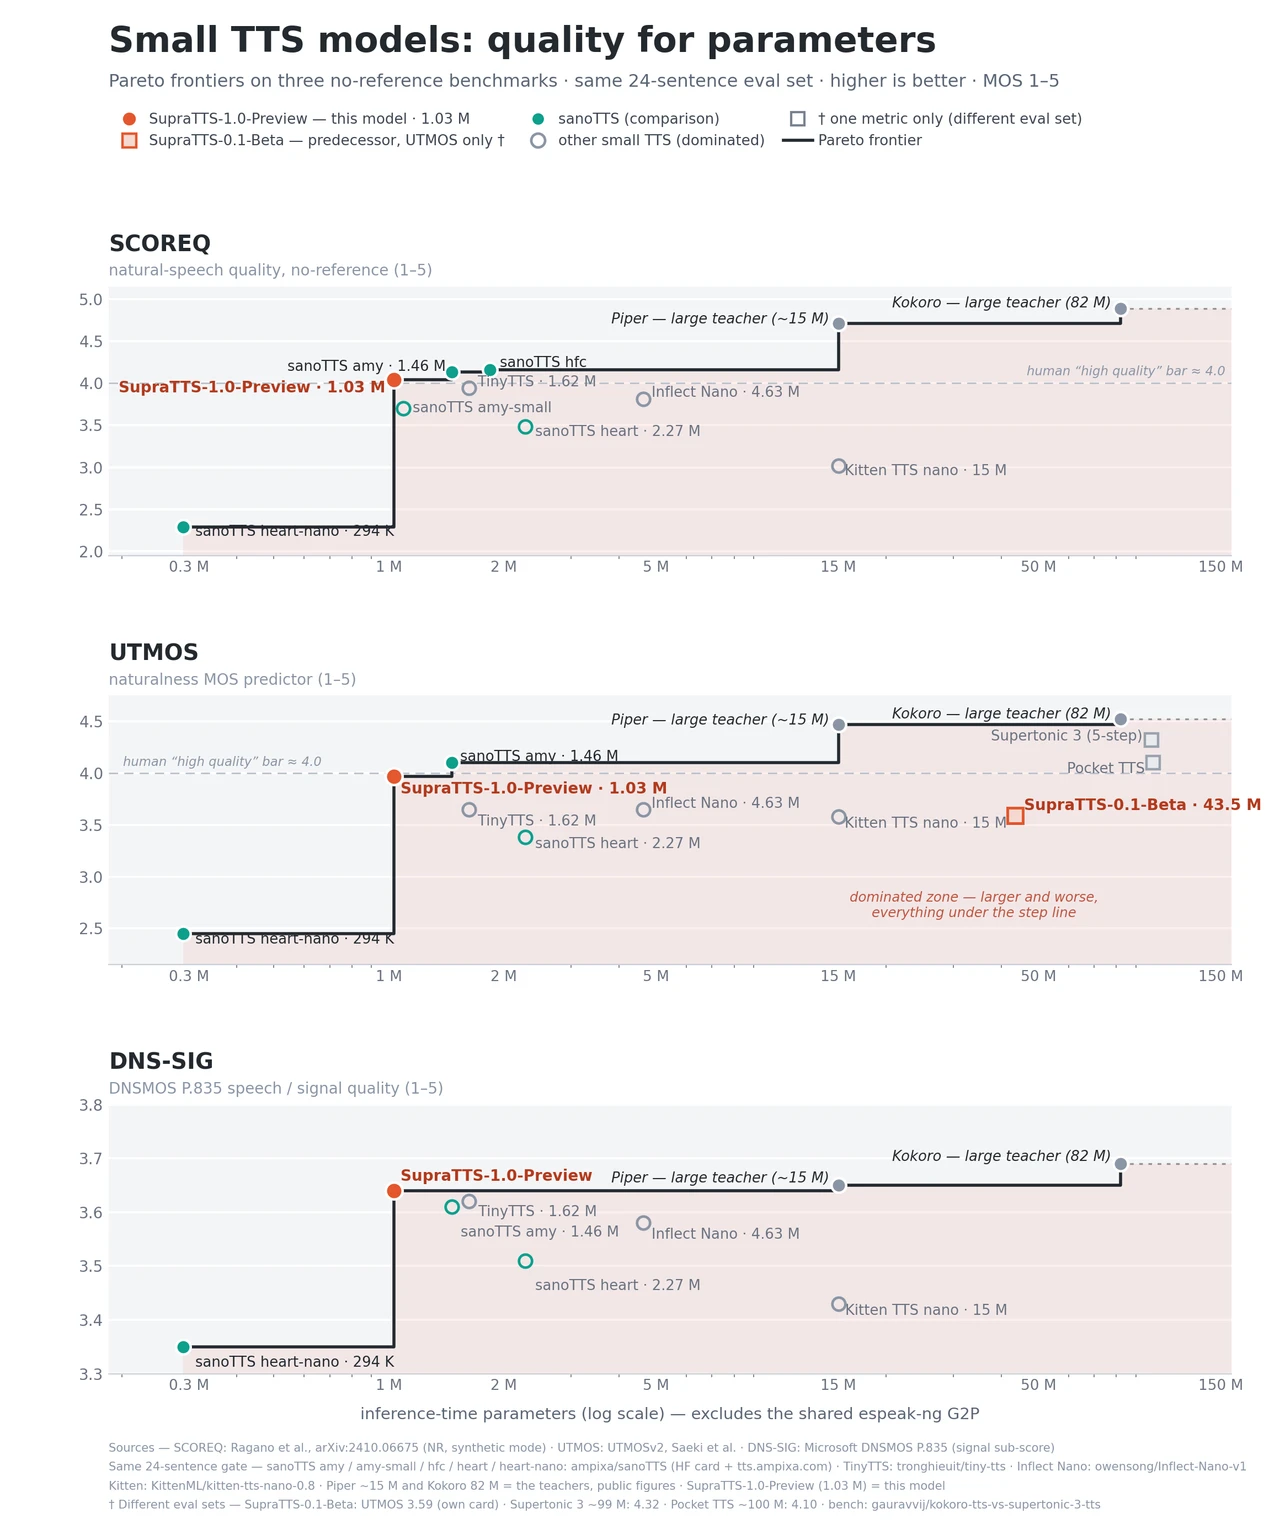
SupraTTS packs an English voice into a 1M-parameter core
Community reports 4 sources
A downloadable English text-to-speech preview with a declared 1.03-million-parameter three-stage core and a local Python runtime.
What happened lately
SupraTTS-1.0-Preview converts English text into 24 kHz mono speech through duration, acoustic and waveform-decoding stages. Its released configuration declares 1,031,754 parameters across that core. A bundled English front end handles grapheme-to-phoneme conversion separately.
The author reports fast CPU synthesis and automatic quality scores on a small evaluation set. These are author-run measurements, not an independent listening test. Hub history begins October 15, 2026, with a private-labelled initial release; the exact transition to public availability is not established by those commit timestamps. The October 17 card update does not imply new model weights.