Launches
Qwen3.8-Flash-Next on one RTX 5090: turboderp claims 200+ tokens/s at 1.66bpw
Community reports 5 sources
Community EXL3 quantizations of Qwen3.8-Flash-Next, including a self-calibrated 1.66bpw branch whose author claims single-RTX-5090 agentic inference with a 64K quantized cache.
What happened lately
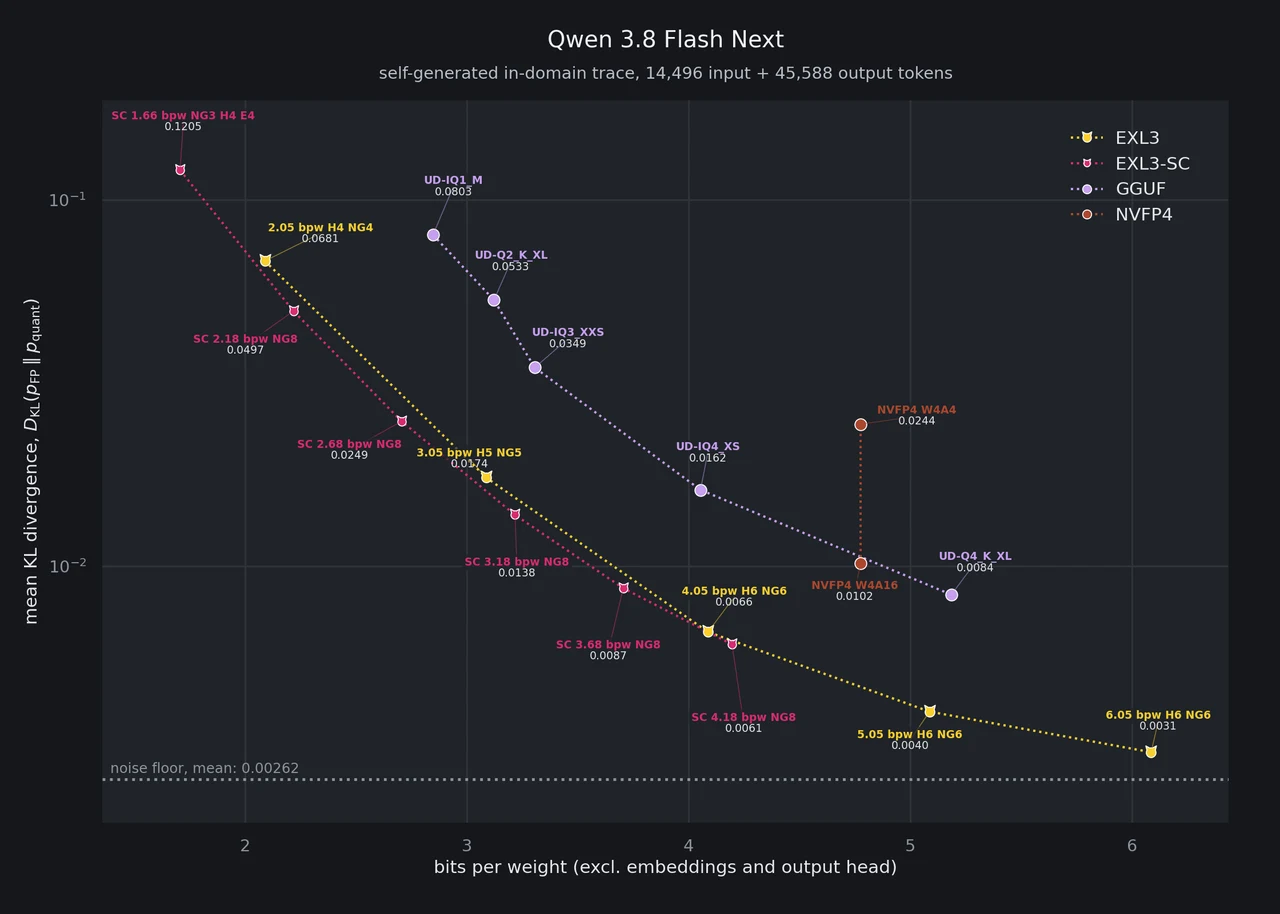
Turboderp publishes plain and self-calibrated EXL3 builds of the existing Qwen3.8-Flash-Next model. The 1.66bpw_h4_ng3 branch received its weight upload on October 20, 2026. Its creator claims more than 200 tokens per second on a headless RTX 5090 with vision, multi-token prediction and a 64K K5V4 cache. These are attributed measurements, not AITrending tests.
The smallest quant mixes expert, head, embedding and vision precisions. Its n-gram table is separately stored and can be streamed from disk. EXL3 requires a compatible runtime such as ExLlamaV3 and is not GGUF. Qwen Community License 1.0 governs the checkpoint, including restrictions for commercial model services and AI work assistants.