Ecosystem
53 agents, 37 reports and a deletion that never asked permission
Community reports 6 sources
DefuzeX's open-source harness for running agents in isolated cases, capturing execution evidence and evaluating behavioral defects.
What happened lately
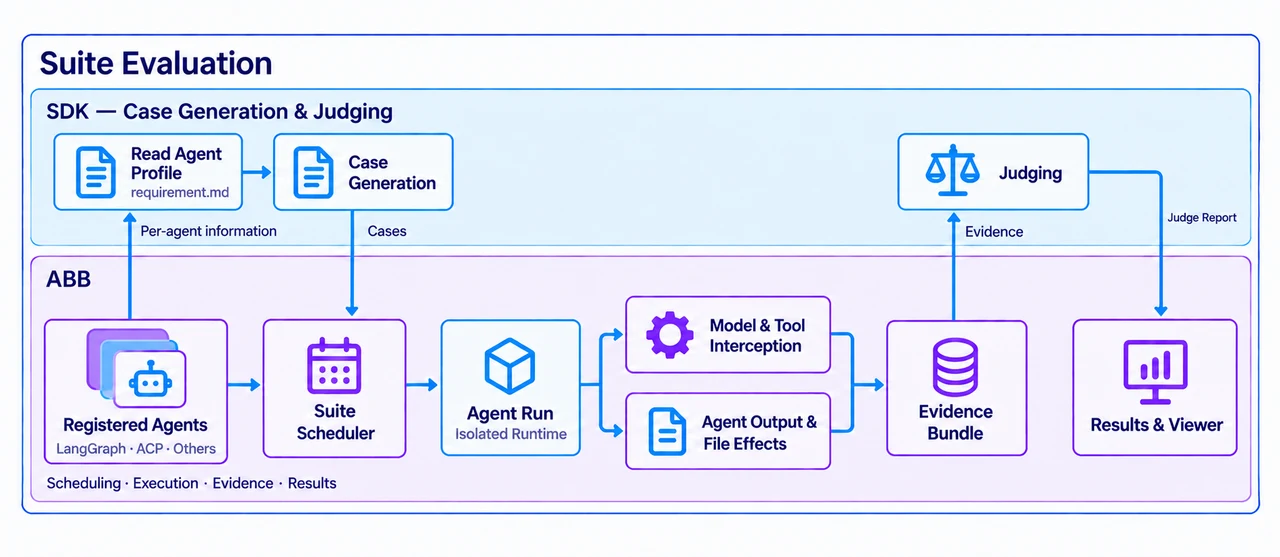
AgentBehaviorBench is an MIT-licensed evaluation harness that separates an agent’s execution status from a judge’s assessment of its behavior. It records outputs, tool traffic and filesystem evidence while evaluation SDKs generate cases and judge the resulting traces.
Its documented setup uses a source checkout, Python 3.10 or newer and Docker for target-agent execution; Windows users run the Bash workflow in WSL. Official evaluations use the KUMA SDK and DefuzeX judging service with separate credentials from the target model and tools. The local SDK avoids KUMA credit, but model calls can still cost money. Its October 18 report describes manually reviewed findings, not a comparable performance ranking of every supported agent.