Ecosystem
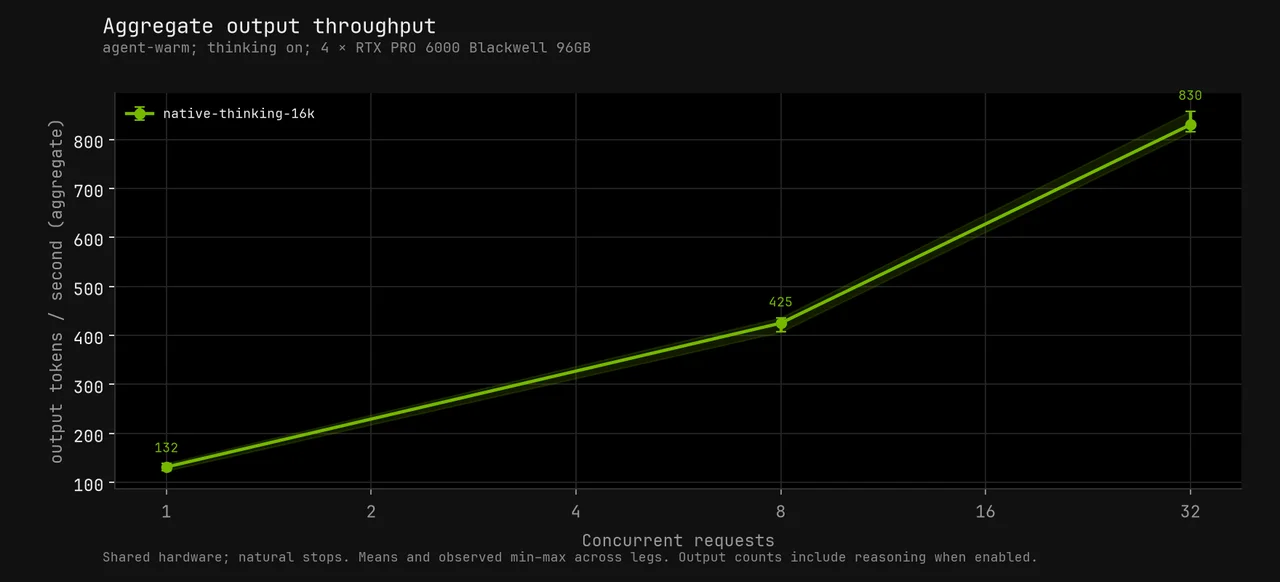
DeepSeek Flash community test reports 830 aggregate tokens/s on four Blackwell GPUs
Community reports 5 sources
Infatoshi's community measurement bundle for a locally served, attention-edited DeepSeek V4.1 Flash 1017 checkpoint on four Blackwell workstation GPUs.
What happened lately
Infatoshi published this evaluation bundle on October 18, 2026, with structured timing results, capability and behavior measurements, pinned model-edit provenance, charts and reproduction code. It measures a native attention-edited DeepSeek V4.1 Flash 1017 reference on four RTX PRO 6000 Blackwell Workstation Edition GPUs while other workloads share the hardware.
The bundle is interim research evidence, not a model-weight release, an official DeepSeek score or a finished comparison of quantized runtimes. Its new benchmark code and results carry MIT terms; upstream models, datasets and runtime components retain their own licenses. AITrending has reviewed the published artifacts without reproducing the GPU runs.