BeeLLM ships a tiny AI hive that shares hidden states
A 50M queen and shared-weight workers coordinate through learned neural links, the author says. Hive needs its own runtime; a separate Scintilla download works with llama.cpp.
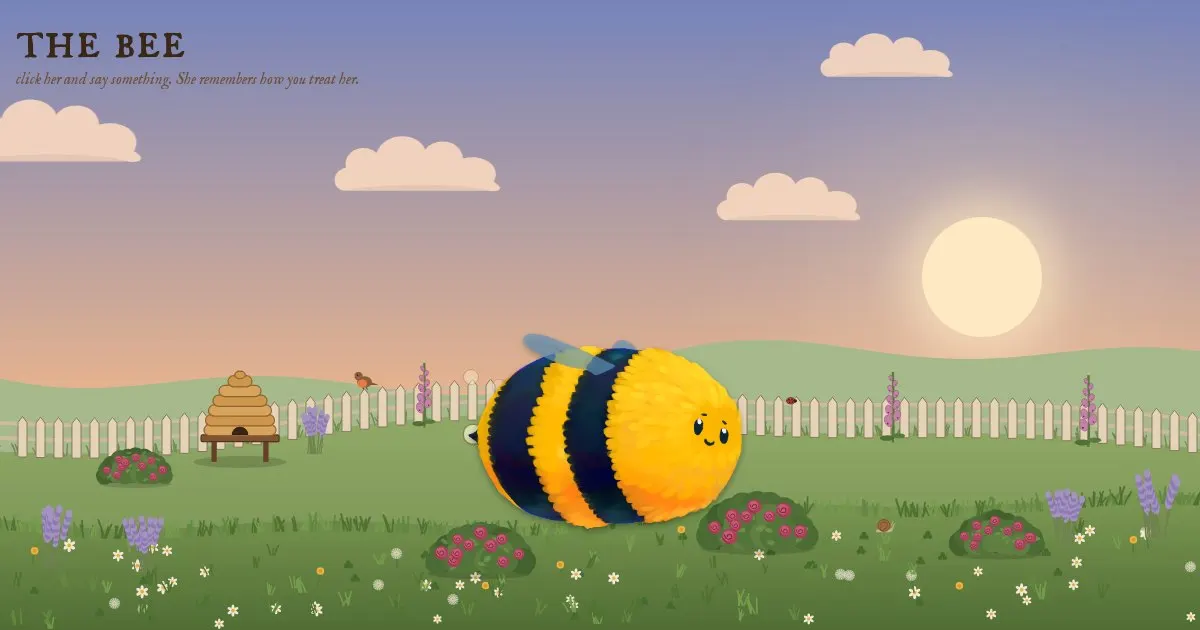
BeeLLM’s latest release turns a tiny conversational model into a hive: a queen and workers that, according to the author, coordinate without reading one another’s chat messages. The new Hive GGUF files and technical notes arrived on November 2 at 23:59:24 UTC. A standalone 50M Scintilla model followed shortly after midnight UTC on November 3.
The project itself dates to October 9. This is a new set of downloadable models and documentation, not evidence that the whole BeeLLM family launched today. AITrending confirmed that the large Hive file’s download endpoint returned 200; it did not run the models or reproduce their coordination tests.
A shared worker brain, separate experiences
The author describes the larger Hive as a roughly 50M-parameter queen, smaller workers sharing one set of weights, and learned links between their internal representations. Each worker has its own context and receives only events that happen to it. The browser experience supports up to 12 workers.
Instead of passing written messages, the models use gated cross-attention between hidden states. The technical notes describe time stamps that prevent a model from copying what another is writing at the same moment. The training environment is a scripted miniature game with events such as finding a flower, feeding a newly hatched worker and responding to a threatened hive.
In the author’s tests across 256 hives with up to six workers, foragers followed the correct flower in 95% of tested lines with the link enabled, versus 0% with it cut. That is an attributed result inside a deliberately trained toy environment. It does not establish general multi-agent reasoning, real insect intelligence or a new capability in arbitrary tasks.
A GGUF file is not always a llama.cpp model
The compatibility distinction matters. BeeLLM-Hive.gguf and BeeLLM-Hive-small.gguf use the custom beehive architecture; the author explicitly says llama.cpp cannot run them. The original site offers a JavaScript browser runtime and an “under the hood” view. AITrending opened the Hive interface, but did not benchmark inference or verify the author’s speed figures.
For ordinary one-to-one local chat, mood/BeeLLM-Scintilla-50M.gguf is the separate queen-only download that the author says supports llama.cpp. The repository lists Apache-2.0 licensing. The large Hive file is about 109 MB and the standalone queen about 201 MB as listed by the host; download size is not a measurement of runtime memory use.
The attraction is a playful, inspectable experiment in sharing internal information between small models. Its documented limits are equally concrete: workers were not trained to answer human messages directly, and the small models can produce garbled or odd replies. Talk to Scintilla, and treat the hive’s behavior as the author’s specialized experiment.
Related reading
Same model, 30% to 81% task completion — IBM's CUGA team makes the case for choosing your harness