StarSkirmish gives AI coding agents an hour to build a StarCraft bot
The refreshed benchmark puts flagship models in their own coding CLIs. GPT-6 Astra leads the author's results, but the strongest human-written bots still dominate.
One hour to turn code into a competitor
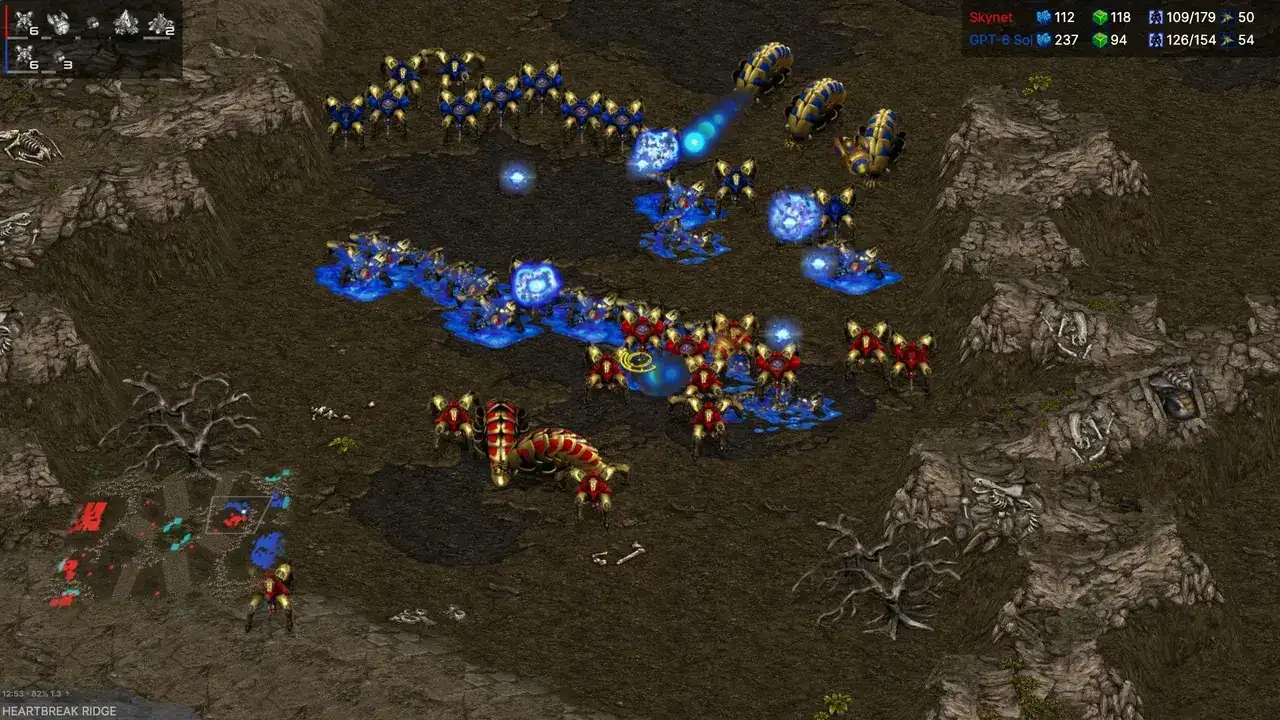
StarSkirmish’s refreshed v0.2 benchmark asks AI coding agents to build a StarCraft: Brood War bot in one hour. The models write Protoss strategy code in C++, compile it and learn from practice matches. This is a test of bot-building through code, rather than a language model directly playing through a visual interface.
The author announced the refresh on October 16. Version 0.2 uses each lab’s own coding harness: Claude Code, Codex, Antigravity CLI and Muse Code. Each model gets five separate attempts. The finished bots face a fixed roster of ten competitive human-written bots and three demonstration bots across three maps. Unlike v0.1, the model-built bots do not play each other, and average win rate replaces Elo scoring.
Astra leads, with a large human-bot gap
The organizer reports GPT-6 Astra in first place and GPT-6.1 Sol in second. Gemini 4 Argon, Claude Opus 5.5 and Claude Fable 5.1 are described as functionally tied, with scores between 37 and 39. That makes the announcement’s Gemini hook interesting without establishing a decisive Gemini win over the Claude models.
The hardest opponents remain far ahead: the page reports that even Astra wins only 7% of games against Stardust, PurpleWave and BananaBrain. These are author-published benchmark results, not an AITrending reproduction or a general ranking of every coding task.
The setup also matters. Agents can practice against scored opponents, but cannot read those opponents’ source code. Web search, web fetching and other internet access are disabled during the timed run. All models use their highest supported reasoning setting; Gemini’s is high, while the others use max. Changing harnesses, scoring and opponent structure means the new scores should not be treated as a direct numerical improvement over v0.1.
Related reading
rStation wants your spare AI agents to join a public research lab
Mosaic reports better web research with fewer agent sessions