Ecosystem
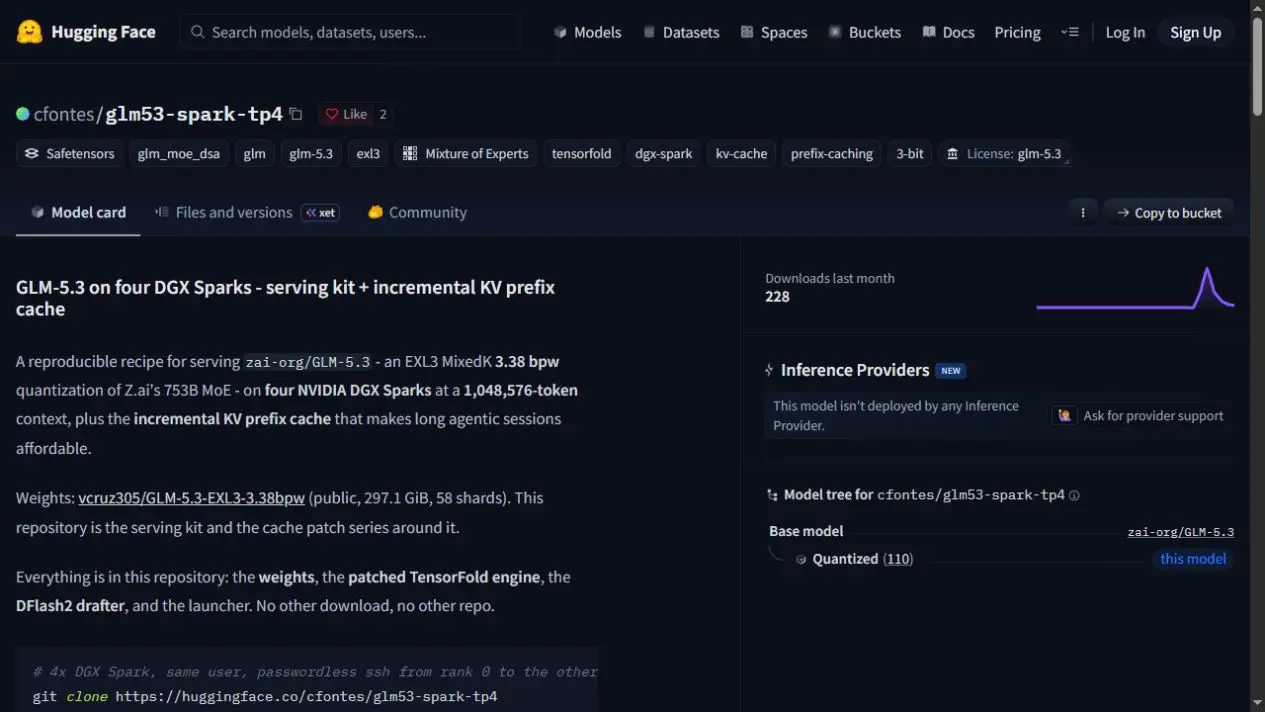
Four Sparks, one huge GLM: a community kit tackles a silent serving stall
Community reports 4 sources
A community TensorFold-based recipe for quantized GLM-5.3 across four DGX Sparks, with incremental prefix caching and component-specific licenses.
What happened lately
Created October 30, 2026, this community kit packages quantized GLM-5.3 weights, a patched TensorFold runtime, a speculative drafter and deployment scripts. A November 4 update changes the follower wake-up failure path. The author describes a four-DGX-Spark, million-token configuration; AITrending has inspected English documentation and source changes but has not reproduced its measurements. Hardware, single-request serving, single-conversation cache and mixed licensing constrain its practical use.