Launches
Tencent's Hy-Nomas puts steerable video worlds within reach of a single RTX 4090
Developing 5 sources
Tencent Hunyuan's interactive video world model, with multi-turn text instructions, camera control, downloadable weights and a documented single-GPU inference configuration.
What happened lately
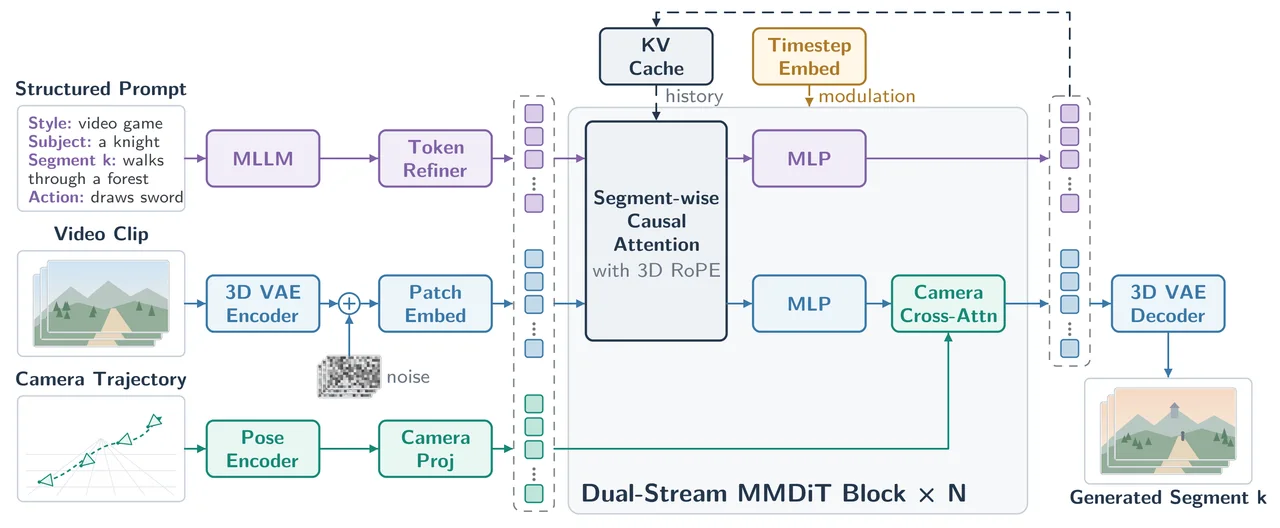
Hy-Nomas generates successive video segments while accepting new text instructions and camera inputs. Its October 27 technical report describes an 8B diffusion backbone and cached interaction history. The model and code repositories provide checkpoints, inference examples and adaptation tools under Apache-2.0, with separate terms for third-party components.
The authors document a single RTX 4090 configuration using quantized weights, bounded GPU history and CPU offload. This is a video-inference claim, not a guarantee that the complete interactive web service fits on that GPU. The web demo also requires a separately served Nomas-PE prompt-enhancement model. Output frame rate and actual generation speed are different measurements.