Launches
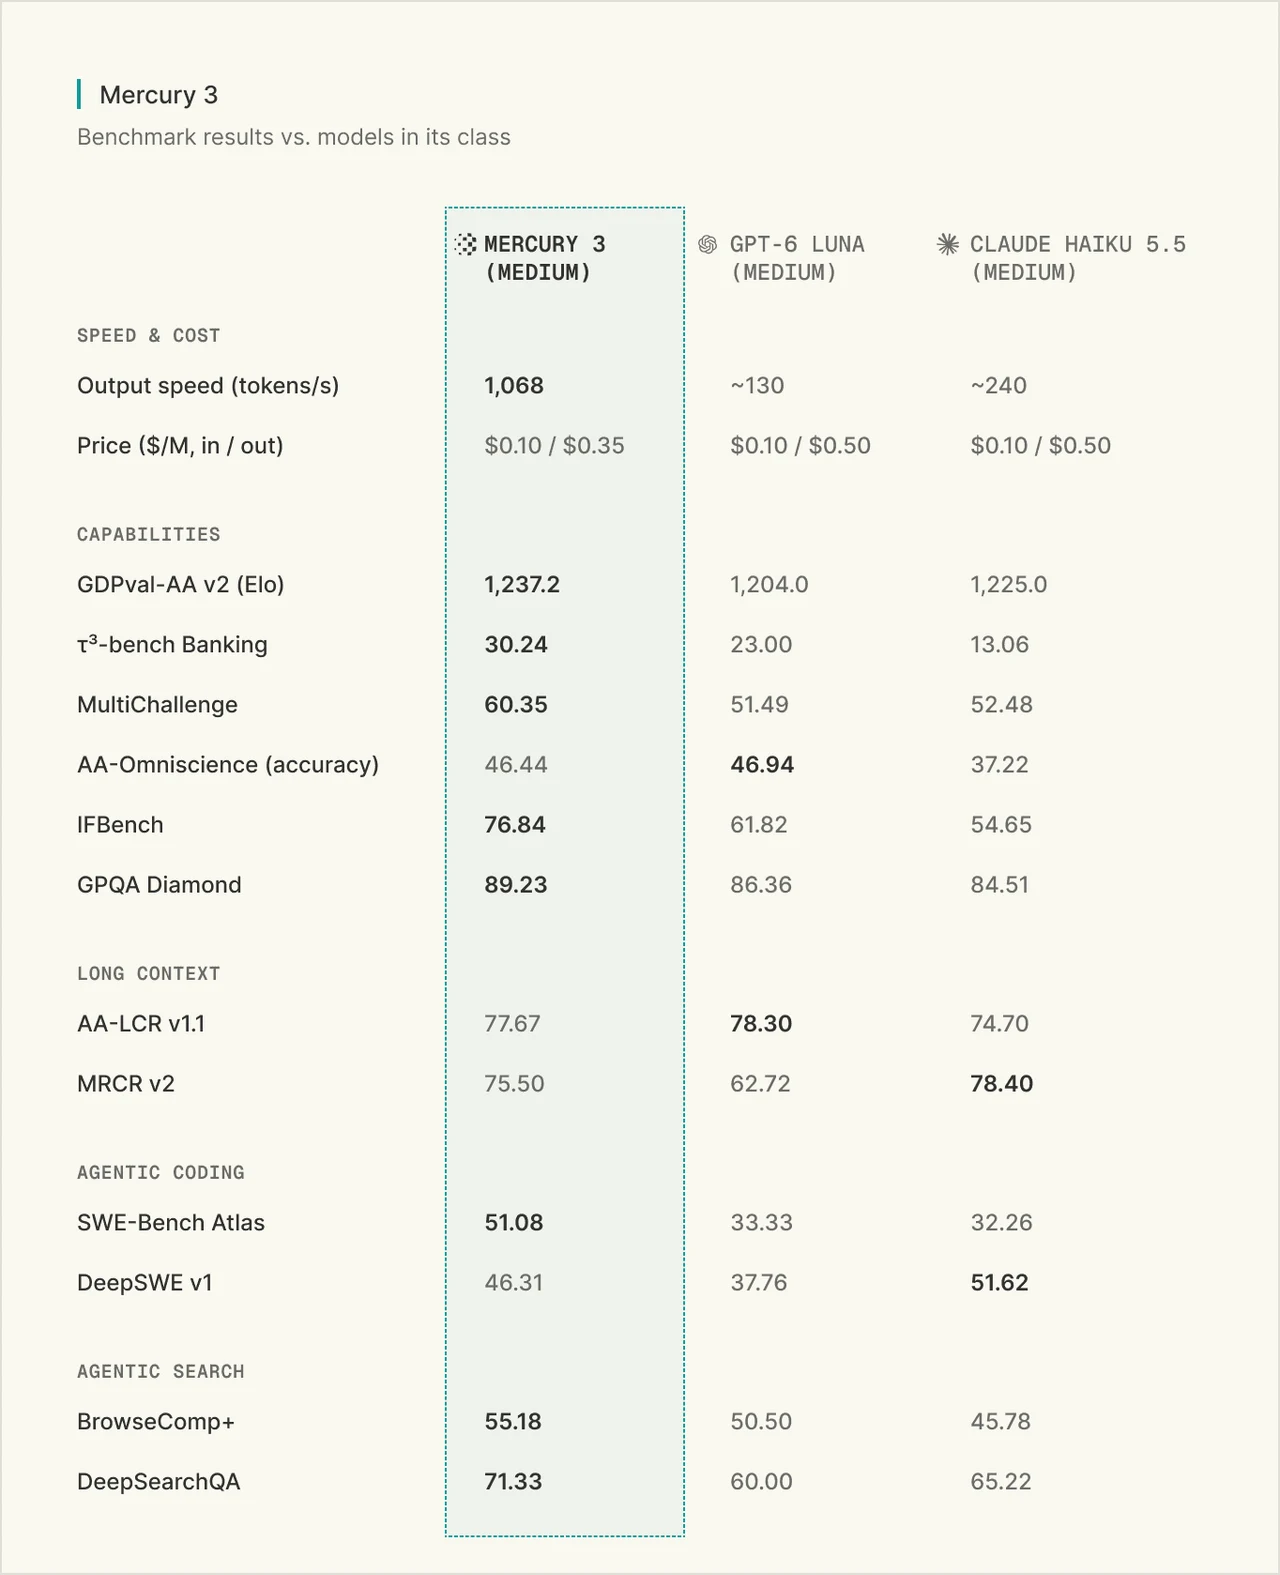
Mercury 3 launches with a million-token context and a 1,068-token/s speed claim
Source-backed 3 sources
Inception's hosted diffusion language model, with a million-token context window and vendor-reported generation speed above 1,000 tokens per second.
What happened lately
Inception announced Mercury 3 on October 19, 2026, with a one-million-token context window and hosted API access. The company reports 1,068 output tokens per second on NVIDIA GPUs and compares its quality with speed-oriented models from OpenAI and Anthropic. Those speed and benchmark figures are vendor claims, not independently reproduced AITrending measurements.
The quick start uses the model identifier mercury-3 at an OpenAI-compatible chat-completions endpoint. Users create an Inception account and API key; the documentation advertises 100 million introductory free tokens. The announcement lists standard pricing of $0.20 per million input tokens and $0.70 per million output tokens, with a 50% launch discount. Availability through a hosted API does not establish that model weights are downloadable or that every workload reaches the advertised generation speed.