Launches
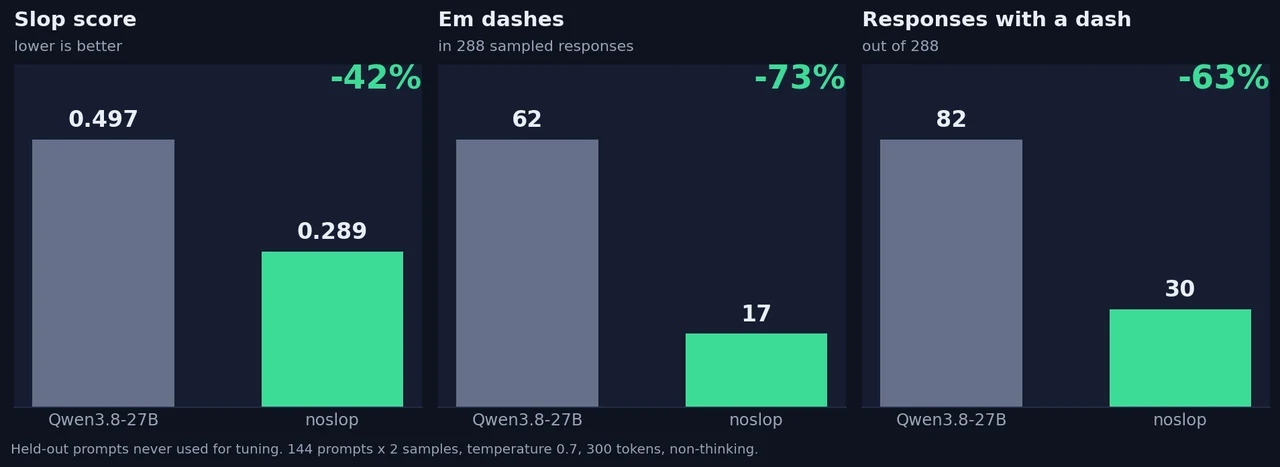
This Qwen remix targets AI writing tics, claiming a 42% lower 'slop' score
Community reports 5 sources
RefinedNeuro's community Qwen3.8-27B weight modification targets formulaic English prose, with author-reported writing evaluations and downloadable GGUF builds.
What happened lately
Qwen3.8-27B-noslop is a community modification of Qwen3.8-27B by RefinedNeuro. It merges a rank-50 adapter produced using Heretic’s Arbitrary-Rank Ablation method into bf16 weights to reduce formulaic final answers in non-thinking mode. The English card declares Apache-2.0 licensing and says the vision tower and multi-token-prediction head remain unchanged.
The author reports a 42% lower score on a custom writing-style detector, with fewer em dashes across sampled English writing prompts. These are author measurements on a narrow evaluation, not an independent finding about writing quality or general intelligence. The card says punctuation improvements did not transfer to coding-agent sessions and reports a possible repeated-verification problem in pi.
At the reviewed GGUF revision, five files were present: Q2_K_XL, Q2_K_M, Q3_K_XL, Q3_K_M and Q4_K_M. The card also describes Q8_0, which was absent from that listing. Downloads span approximately 9.83 to 16.81 GB; these are file sizes, not complete memory requirements. AITrending has not run the weights.