Launches
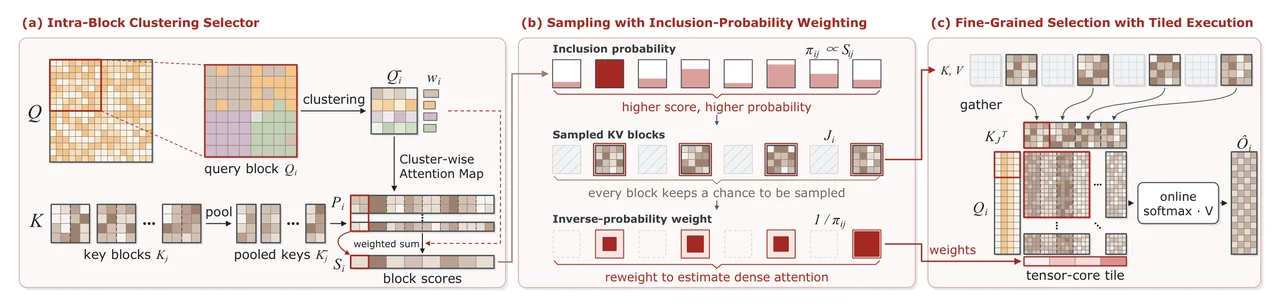
AB-Attention reports up to 2.23x faster video generation by skipping most attention
Community reports 2 sources
Training-free sparse attention research for video diffusion, with public kernels targeting NVIDIA Hopper GPUs.
What happened lately
AB-Attention, or Accurate Block Attention, approximates dense attention in video diffusion transformers using local query clustering, probability-corrected block sampling and tiled GPU execution. It is training-free and the public implementation is MIT licensed.
The authors report matched video-generation tests on Wan2.1 and HunyuanVideo, with speed measured against dense FlashAttention-3 runs on NVIDIA H20. The public package targets Linux, Python 3.10 or later, PyTorch 2.6 or later, CUDA 12.4, GCC 12 and Hopper GPUs with sm_90a support. Those requirements do not establish support for consumer graphics cards. AITrending has not reproduced the benchmarks.