Launches
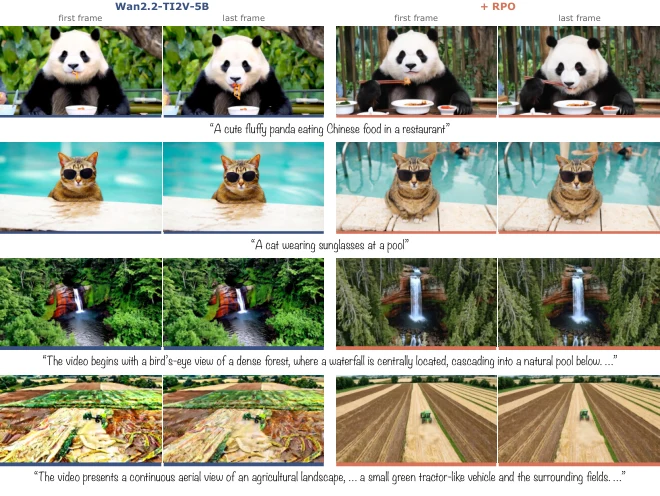
RPO reports up to 4.2x lower video RL training cost by routing attention
Community reports 3 sources
A research method that explores temporary attention routes during reinforcement learning of image and video generators, then restores dense attention at inference.
What happened lately
Routing Policy Optimization, or RPO, moves stochastic exploration into attention during online reinforcement learning. Matched rollouts share the prompt and starting noise but use different attention routes. Their reward difference supplies a learning signal; the updated generator returns to dense attention and its original deterministic sampler at inference.
The October 15, 2026 preprint reports experiments on Stable Diffusion 3.5 Medium and Wan2.2-TI2V-5B. Its video training used 24.1 H100 GPU-hours, compared with 75.4 for Flow-GRPO and 102.3 for DanceGRPO in runs that were not compute-matched. These are training measurements, not inference speedups. The public project page lists training code and evaluation outputs as planned; AITrending has not reproduced the results.