Teach your transcriber 2,000 names: IBM updates Granite Speech for multilingual work
IBM's new 2B speech model expands keyword biasing and language control, while separate Turbo CTC and meeting-transcript models receive revised capabilities.
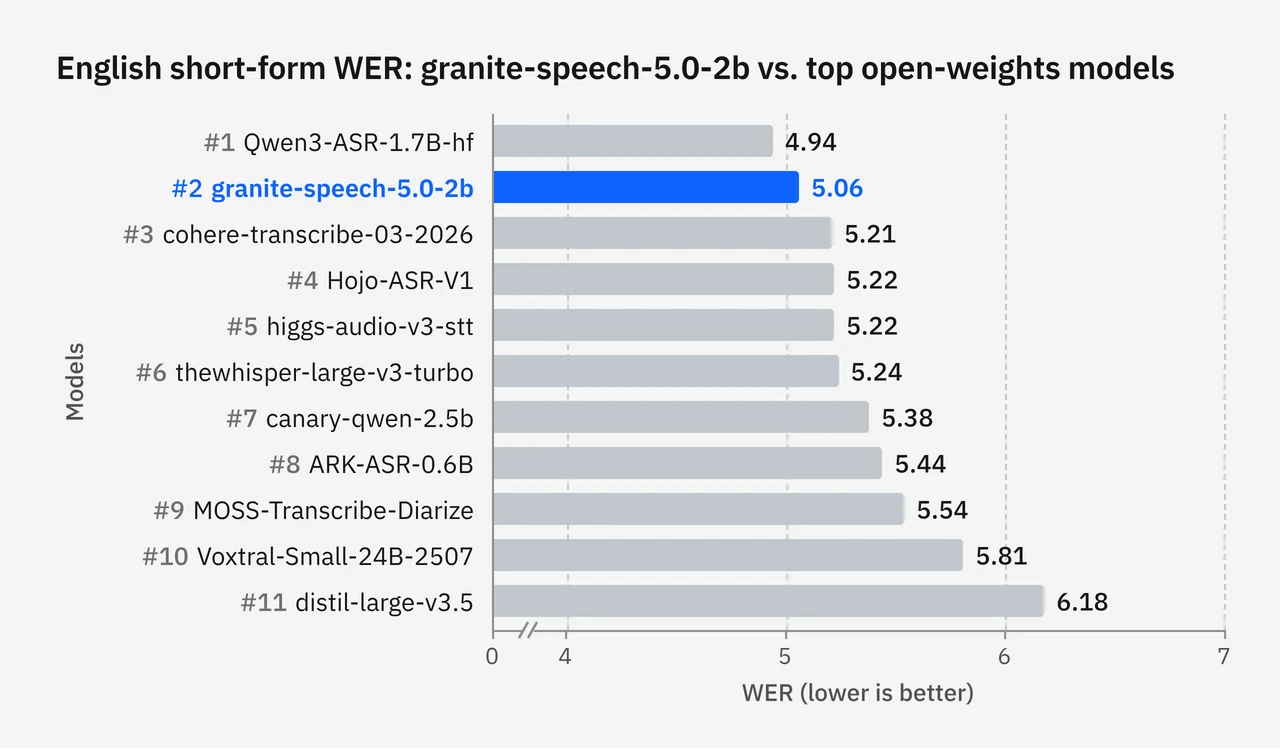
Product names, people and acronyms are the hook for IBM’s Granite Speech 5.0 2B: it accepts keyword lists of up to 2,000 terms to steer transcription and translation. IBM’s October 21 announcement pairs that new model with updates to its fast Turbo CTC transcriber and speaker-attributed meeting model. The 2B model card dates its release to October 20.
Keyword biasing guides recognition toward supplied terms; it does not guarantee every name will be correct. The new 2B model also accepts a prompt naming the input language and instructions for punctuation and capitalization. IBM says it improves handling of noisy, reverberant and distant-microphone speech, plus longer and conversational translation, at the same parameter count as its 4.1 predecessor.
It transcribes English, French, German, Spanish, Portuguese and Japanese. Translation runs to and from English for those languages, with English-to-Italian and English-to-Mandarin also documented. This is a defined language set, not universal speech translation.
Choose the model for the recording
The updated 470M Turbo CTC model targets throughput and on-device transcription. IBM says it now supports seven transcription languages, adding native punctuation and capitalization and more robust reverberant-audio handling. Its reported 19,870 real-time factor on the English short-form Open ASR evaluation measures benchmark throughput, not a promise of that speed on a laptop or every recording.
For meetings and calls, the revised Granite Speech 4.1 2B Plus retains its architecture, prompt format and API while changing weights. IBM reports timestamp error dropping from 210.86 to 98.54 on its all-speech comparison, and long-form word error rate from 13.53 to 10.22. These are the developer’s evaluations; AITrending has not reproduced them. They also concern that separate Plus model, not automatic speaker attribution in every 5.0 variant.
Local deployment still has practical limits
IBM declares Apache 2.0 licensing and documents Transformers, vLLM, llama.cpp and Apple Silicon mlx-audio routes for the new 2B model. Its card recommends audio segments of about two minutes or less, splitting longer recordings before decoding. For llama.cpp it recommends Q8_0 and warns that lower-bit quantization loses accuracy on audio longer than about a minute. The mlx-audio example requires version 0.5.9 or later and a separate jinja2 install.
These changes add speech-specific choices beyond the earlier Granite Switch configuration that combined chat, decision adapters and an English transcription encoder. An existing Switch endpoint should not be assumed to inherit the new multilingual weights or meeting features automatically.