TorchNeuron brings native PyTorch to Trainium, with public beta due October 20
AWS pitches a simpler route off hardware-specific code, while Hugging Face recommends using its standard libraries directly on the new neuron backend.
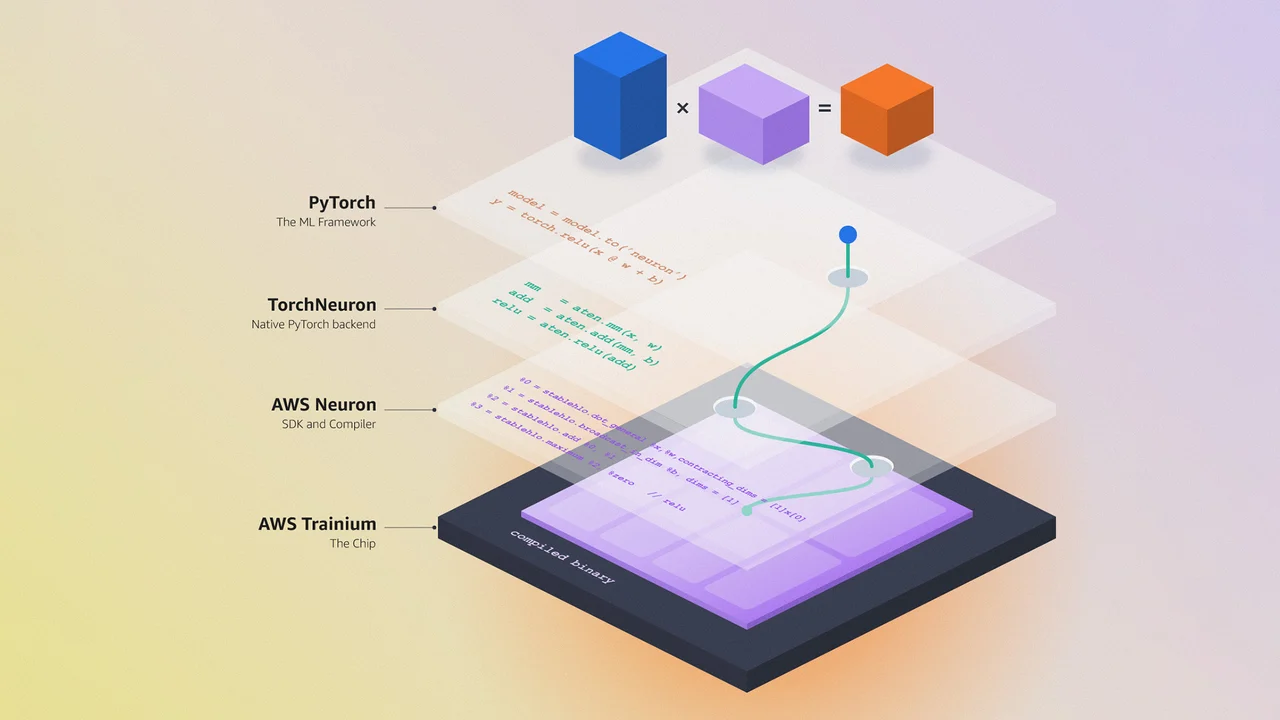
AWS wants moving PyTorch code to Trainium to feel like choosing another device. Its October 19 TorchNeuron announcement introduces a native PyTorch backend, while Hugging Face says developers can use its main model libraries directly instead of going through Optimum Neuron’s custom classes.
The timing matters: Hugging Face schedules the public beta for October 20, 2026, and Amazon says the Apache 2.0 open-source release will take place at PyTorch Conference North America that day. This is an announced release with a forthcoming beta, not confirmation that public access is already available on October 19.
What changes for builders
TorchNeuron exposes neuron as a native PyTorch device, with eager execution, torch.compile and distributed primitives including DTensor and FSDP2. Hugging Face now recommends using Transformers, Diffusers, Accelerate, PEFT and TRL directly on the backend. Its guide includes text-generation, fine-tuning and image-generation examples.
Hugging Face says the backend supports 89% of the top 100 most-used text-generation model architectures, compared with 46% for Optimum Neuron v0.4.5. That is the integration team’s compatibility comparison, not an AITrending benchmark or a guarantee for every model and operation.
The announced installation route is pip install torch-neuronx starting with the beta. Amazon says TorchNeuron supports Trainium2 and Trainium3. Developers still need appropriate Trainium compute and should account for cloud-instance costs; this is not a new model or a replacement runtime for a laptop’s CPU or GPU.
The portability pitch has practical limits
Amazon describes existing code running with a single configuration change. Hugging Face’s worked examples give that claim useful boundaries: the training example disables automatic dynamic shapes, uses padded or packed sequences to limit recompilations, and turns off unsupported asynchronous weight loading with HF_DEACTIVATE_ASYNC_LOAD=1. Its generation example recommends a static cache.
For teams already using the Hugging Face stack, the concrete opportunity is testing familiar training and inference code on Trainium with fewer dedicated framework classes. Whether a particular workload is faster or cheaper still requires measurement on its actual model, shapes and instance configuration.