Ecosystem
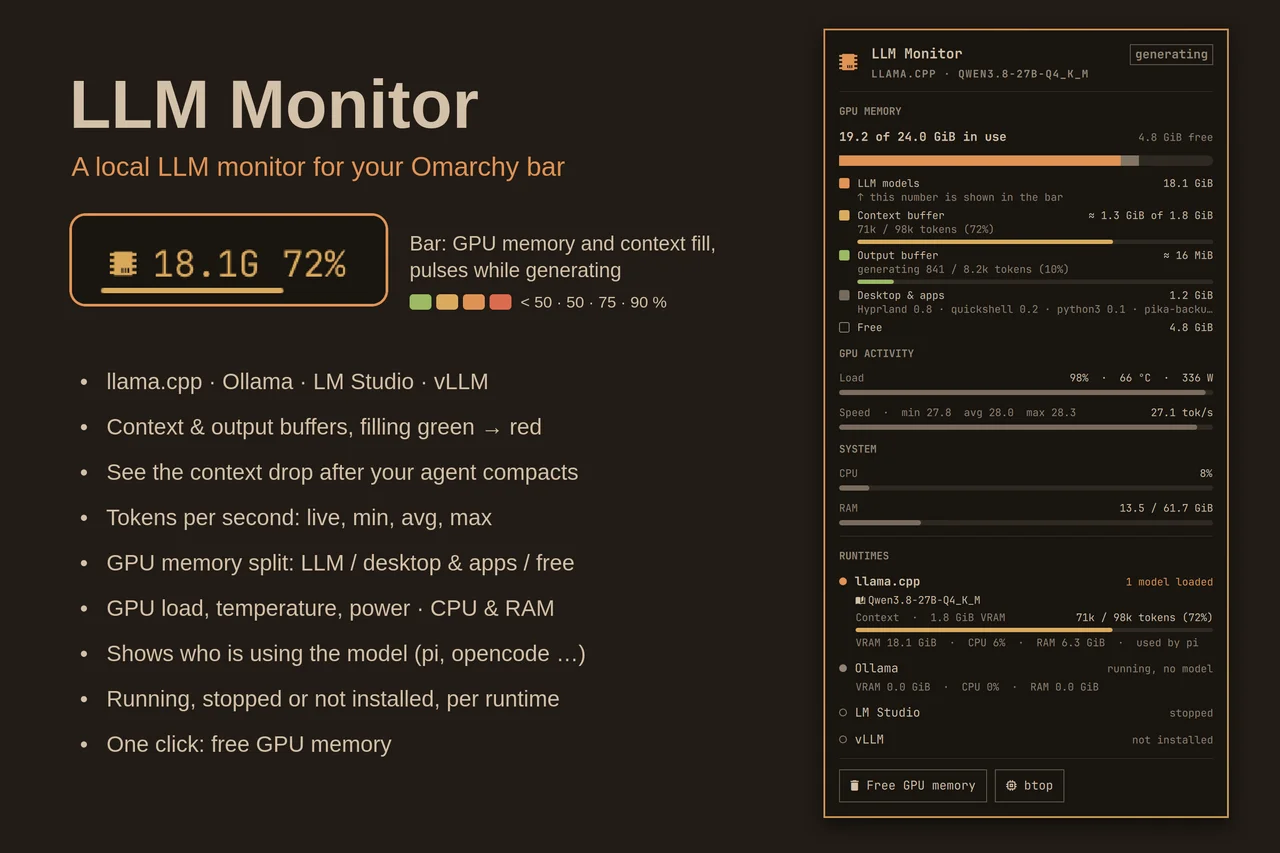
LLM Monitor puts local AI memory in your bar, then reins in runaway polling
Community reports 4 sources
An Omarchy Quattro bar plugin that monitors local model memory, context usage, runtime activity and connected clients.
What happened lately
LLM Monitor is an MIT-licensed local monitoring plugin for plugin-capable Omarchy Quattro and Quickshell, with a Python 3 standard-library collector. It supports llama.cpp, Ollama, LM Studio and vLLM. It is neither a model provider nor an agent harness: it reports on runtimes used by other applications, including coding agents.
The documented installation uses omarchy plugin add https://github.com/uBruckhaus/omarchy-llm-usage followed by omarchy plugin enable ubruckhaus.llm-usage. Monitoring reads local process information and localhost runtime APIs without a cloud-provider key. GPU metrics use AMD amdgpu interfaces; other hardware may lack those fields. Runtime-specific context and output statistics are not identical.
The optional Free GPU memory action changes runtime state: it stops supported user services or unloads LM Studio models, affecting other clients of those runtimes. Version 0.4.1 bounds model lists and per-snapshot follow-up requests. The marketplace submission still required a maintainer’s security review when checked.