Ecosystem
SelfBench makes timed-out coding tests count as failures
Community reports 4 sources
An MIT-licensed coding-agent evaluation platform that builds reviewable tasks from merged pull requests and compares model and harness settings by accuracy and cost.
What happened lately
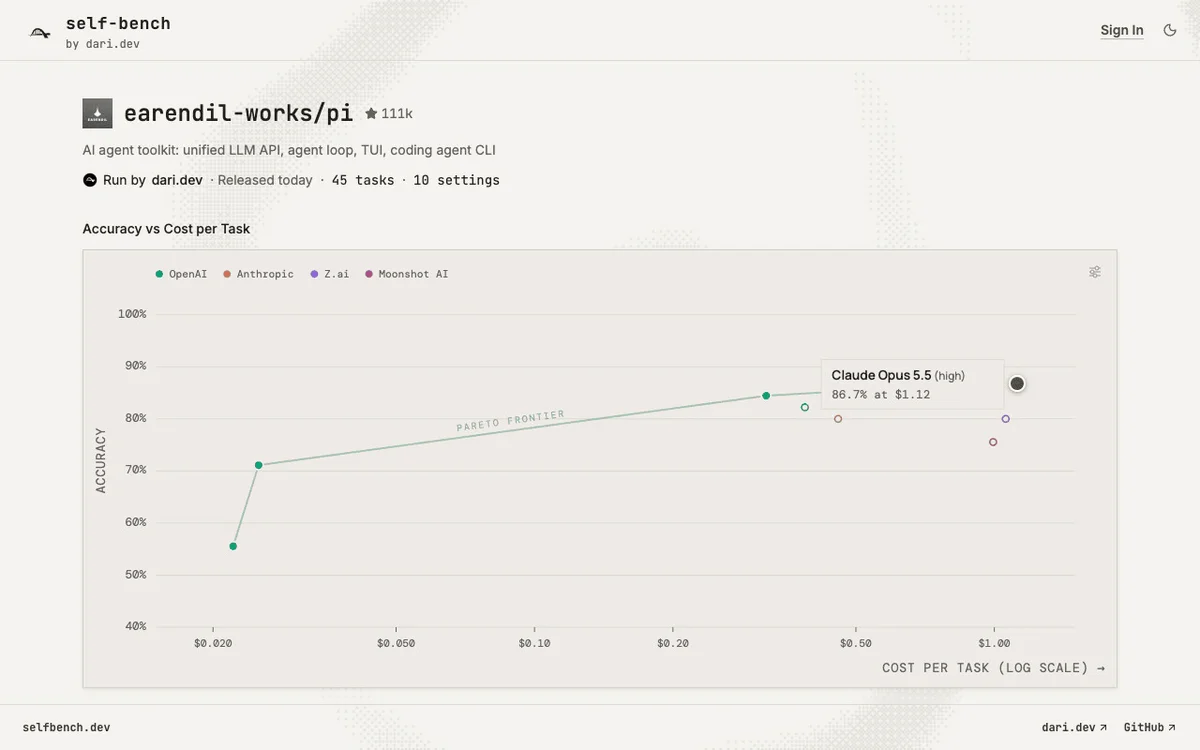
SelfBench turns merged repository pull requests into coding-agent tasks with instructions, hidden tests and reference solutions. Users review generated tasks before comparing model and harness configurations in sandboxes. Public repository results can be released as accuracy-versus-cost leaderboards.
The web application uses GitHub sign-in and workspace credentials for model and sandbox access. The source is MIT licensed. Local development requires Bun and Docker Compose; the documented reference production deployment uses GCP infrastructure. Repository access and evaluation credentials are operational requirements, not evidence that a benchmark is representative of every software project.