Ecosystem
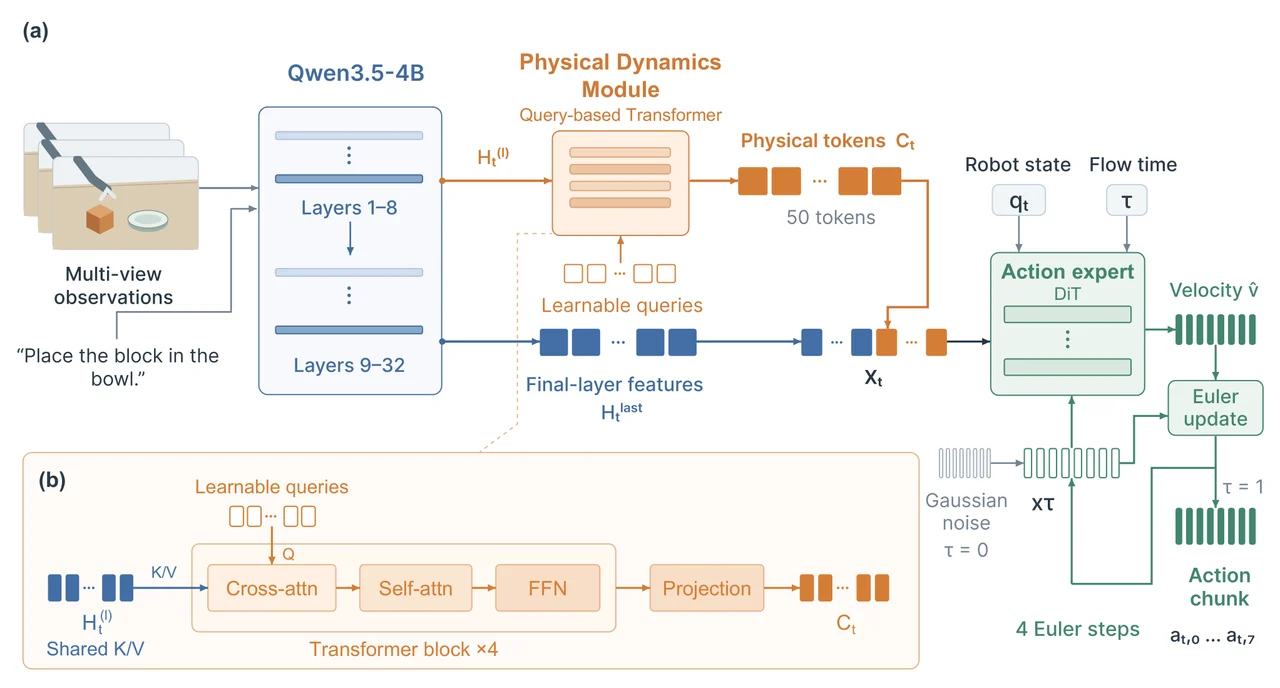
PDRVLA teaches robot actions without generating video at run time
Community reports 2 sources
A robotics research framework that learns future physical features during training and removes the auxiliary video model at execution.
What happened lately
PDRVLA trains a vision-language-action system to represent future physical consequences through compact physical tokens. Its auxiliary objectives predict RGB, depth and optical-flow features. At execution, the auxiliary video model and prediction heads are removed, while learned physical tokens condition an action expert.
The authors report benchmark-specific fine-tuning and simulation evaluations on LIBERO, LIBEROPlus, RoboTwin 2.0 and SimplerEnv. Their comparisons draw on baseline results under the respective published protocols. These are author-reported research findings, not independently reproduced AITrending results or evidence of real-robot reliability. The paper first appeared on October 27, 2026; a downloadable implementation or weights release was not established during review.