FLUX 3 Klein gets GGUF builds starting at 2.74 GB
Molbal published distilled and base GGUF checkpoints with ComfyUI workflows, giving local image creators another quantized route into Klein.
Storyline / Report 4 of 4
FLUX 3 Image Klein release, customization and local builds
Full timeline 4 reports
- Source-backedFLUX 3 Image Klein brings box-controlled image editing to downloadable weights
- Community reportsKlein Trainer puts FLUX 3 LoRA training in your browser, with the GPU bill on your account
- Community reportsA 5.72 GB FLUX 3 Klein build targets laptops, with a 1.64x speed claim and a ComfyUI patch
- Community reportsFLUX 3 Klein gets GGUF builds starting at 2.74 GB (current report)
A smaller download for the local image workflow
Community maintainer molbal has released GGUF quantizations of FLUX 3 Image Klein’s distilled and base checkpoints, along with text-to-image and image-editing workflows for ComfyUI. The smallest listed distilled file, Q4_CR, is 2.74 GB; Q4_CR_L is 2.78 GB and Q4_K_M is 2.91 GB. Base-model options start with a 2.90 GB Q4_K_M file.
The upload history places the repository’s creation and the two weight batches on October 16, between 20:53 and 20:55 UTC. This is a separate community packaging release, rather than a claim that Black Forest Labs launched Klein again.
The card recommends Q8_CR for GPUs with native INT8 acceleration. It describes Q4_CR_L as packed INT4 weights with INT8 activations and additional sensitive attention projections kept in Q8_CR; Q4_CR uses INT4 weights and activations. Those are the maintainer’s format and deployment recommendations, not an independently measured quality ranking.
The GGUF file is only one part of the pipeline
Installation uses ComfyUI v0.41 or later, the comfyui-gguf-reboot custom nodes and their UnetLoaderGGUF loader. Users also need the separate Qwen3-VL 4B text encoder, the FLUX VAE and the appropriate prompt-expansion setup. CLIPLoader must use the flux3 type. The repository supplies importable workflow JSON files.
A 2.74 GB transformer file does not mean the complete pipeline needs only 2.74 GB of VRAM. Encoder, VAE, activations and any prompt-upsample model add requirements; these sources do not establish an independently tested minimum GPU configuration.
Prompting also matters. Molbal recommends full scene descriptions or the Qwen3.5 9B prompt upsampler. In a separate public discussion, BFL acknowledged a Comfy workflow error on October 15 and said prompt upsampling should always be used; its October 16 reply pointed users to updated v0.41.2 workflows. The community card’s optional-upsample wording should not be read as a promise of equivalent results from short prompts.
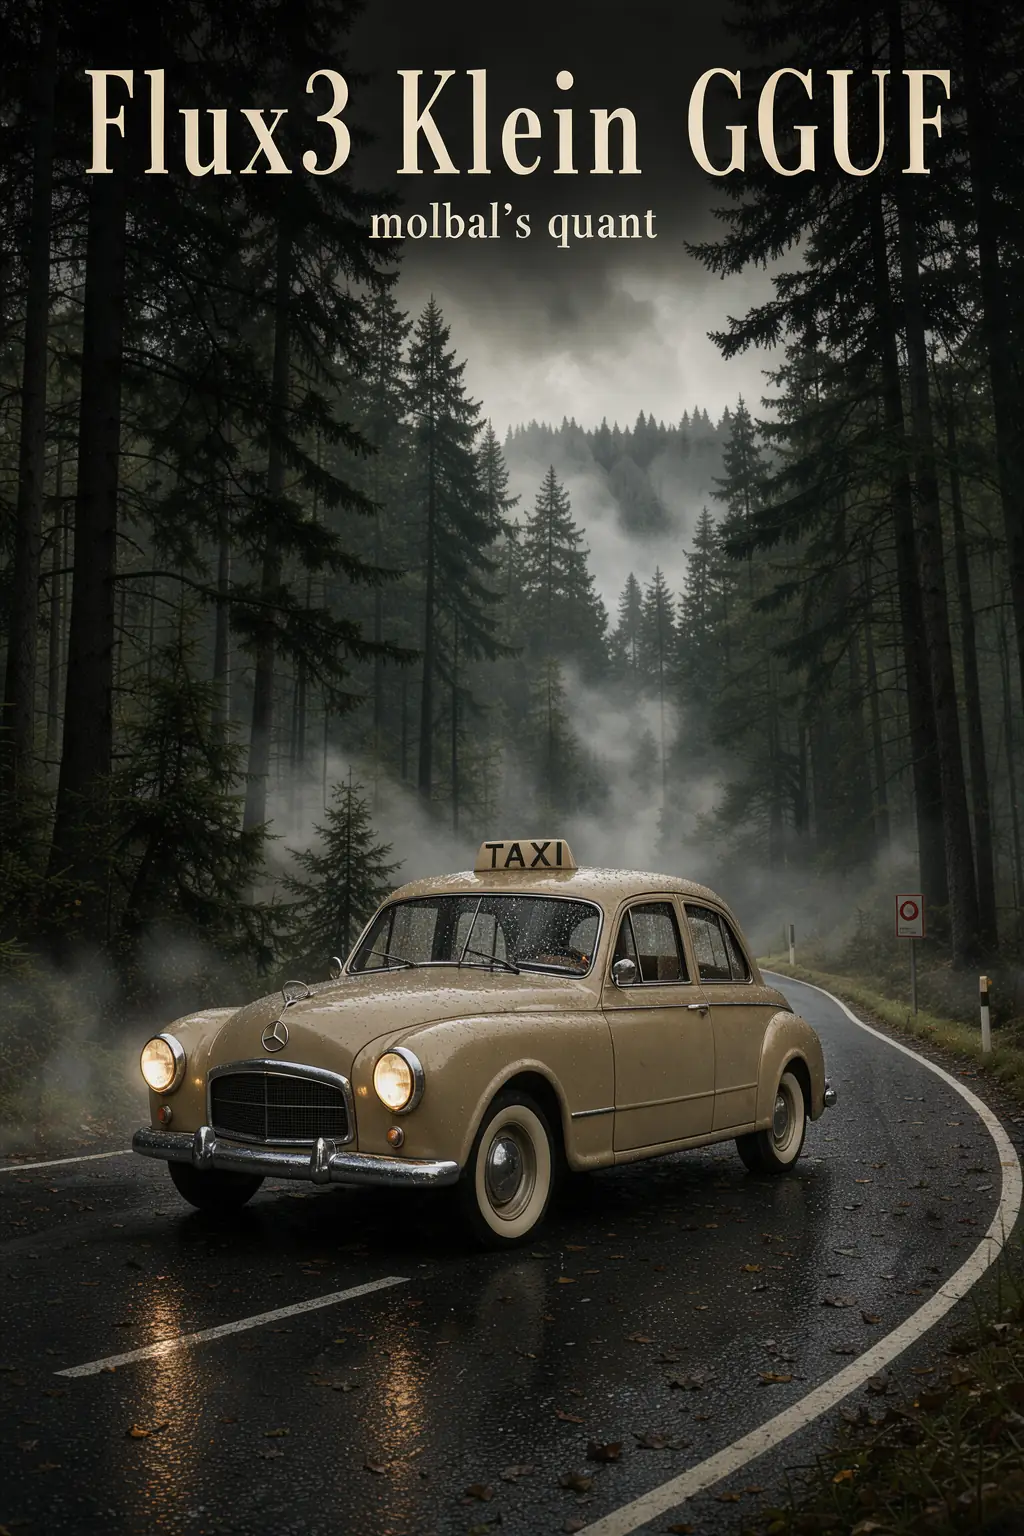
The base and distilled checkpoints retain Klein’s generation and reference-editing design. The release remains subject to the FLUX Kommunity License, including its restrictions, rather than becoming permissively licensed through GGUF conversion. The author-published illustration is a sample, not an AITrending reproduction or comparative benchmark.
Related reading
SCOPE trains better image prompts without retraining the generator
Meta's 816B Muse Spark Open fits a 512GB Mac with a 304GB GGUF